October 11, 2026
Local AI and the GDPR: Danish research could make a real difference for businesses
Danish lab Sevren gains access to the Gefion supercomputer and is working to make AI models more efficient. The interesting part is not the price, but what it could mean for companies that want to use AI on their own data without losing control of it.
It is easy to build an impressive AI demo with ten made-up customer emails. It gets considerably more interesting when the system has to read ten thousand real ones.
Because then names, prices, agreements, order numbers, personal data and internal messages come with them. And suddenly the AI project is not only about how well the model answers. It is also about where the information is processed, who can see it, and what the system is allowed to do with it.
That is why I think a new Danish AI agreement deserves attention. Not because it solves every problem. But because it points in a direction that could matter to far more businesses than those developing AI themselves.
What happened at Sevren and DCAI?
On 9 September 2026, the Danish Centre for AI Innovation (DCAI) announced an agreement with the Danish AI lab Sevren. Sevren gains access to the Danish AI supercomputer Gefion, including NVIDIA DGX B300 systems with Blackwell Ultra GPUs.
Sevren grew out of the AI work at the Danish fintech company Monthio. The lab launched on 26 August 2026 and works on technologies intended to make advanced models less demanding to develop and run.
Two names matter here:
HEIMR
Sevren's work on more efficient model architectures. It is an alternative to the mechanism that decides which parts of a text the model should pay attention to. The goal is less compute and memory — and being able to run demanding tasks with very long context on smaller equipment.
Faberon
A research and optimisation engine meant to support developing and sharing new methods, so European AI developers get more out of limited computing resources.
Sevren reports that early experiments on Gefion have produced substantial efficiency gains on rebuilt open models without a corresponding drop in measured quality. Those are promising but preliminary results. They are not evidence that every large AI model can now run cheaply on an ordinary computer.
From supercomputer to local AI — why are they connected?
Gefion is a large research and development platform. It should not be confused with a local AI server at an ordinary company. The connection lies in what gets developed on it.
In September, for instance, Sevren published Heimr 570M, an experimental language model aimed at phones and laptops. The model has roughly 2.7 billion parameters in total, but uses around 570 million actively for each piece of text it processes.
In Sevren's own measurements it generated text two to eight times faster than selected comparable small open models when the context was long. That is a concrete technical result measured under particular conditions, not a promise of similar improvements on every task. The model is still experimental, and speed alone says nothing about how reliable it is for, say, customer service, law or finance.
But the direction is interesting: if more useful AI tasks can be handled with less hardware, it becomes more realistic to run parts of the solution on the company's own machines, or in an environment the company controls. And that is where the data side really enters the picture.
The central question is not only which model you choose
Picture a company that wants to use AI to sort incoming email, find relevant information in its ERP system and prepare replies to customers. There are several ways to build something like that.
An ordinary cloud service
The material is normally sent to the supplier's system. That need not be a problem. A serious business offering can have appropriate agreements, security measures and clear terms for use and storage.
A contained, hosted solution
More control over the environment, over who has access, and over where processing happens. But suppliers, sub-processors and any transfers still have to be examined.
A properly configured local model
The AI processing itself happens on the company's own servers, without the content being passed to an external AI supplier. Interesting where there are confidential agreements and business-critical knowledge.
But running locally is not automatically better. A local server with poor access control and missing updates can be a worse choice than a well-run cloud solution with sound data processing terms.
What matters is not whether there is a server in Denmark. It is whether the company has a grip on the whole data journey.
Local AI does not make a company GDPR compliant
This is worth stating plainly, because it is where the marketing tends to get too simple.
A model running in your own server room does not exempt you from the GDPR. Personal data must still be processed for a lawful purpose, on a valid legal basis and with appropriate security. You have to limit access and avoid processing more information than the task requires.
If you use external suppliers as data processors, the agreements and responsibilities have to be in place. And for high-risk processing there may be a requirement for an impact assessment before the system goes live.
This follows, among other things, from the GDPR's rules on data minimisation, legal basis, processors and security. The European Data Protection Board has also stressed that questions about AI models and personal data must be assessed case by case. Calling a model "anonymous" does not necessarily make it anonymous.
Nor is it enough to switch off model training on your own data. Information can still appear in queries, log files, search indexes, backups and integrations.
And if there is no policy, which there often is not, that does not mean everything is permitted. It means nobody has taken a position.
From my book AI i hverdagen, chapter 25 on privacy and security, page 240. The book is in Danish.
That point applies all the more when AI moves out of an individual employee's chat window and into the company's systems.
A concrete example: from customer email to a draft in the ERP system
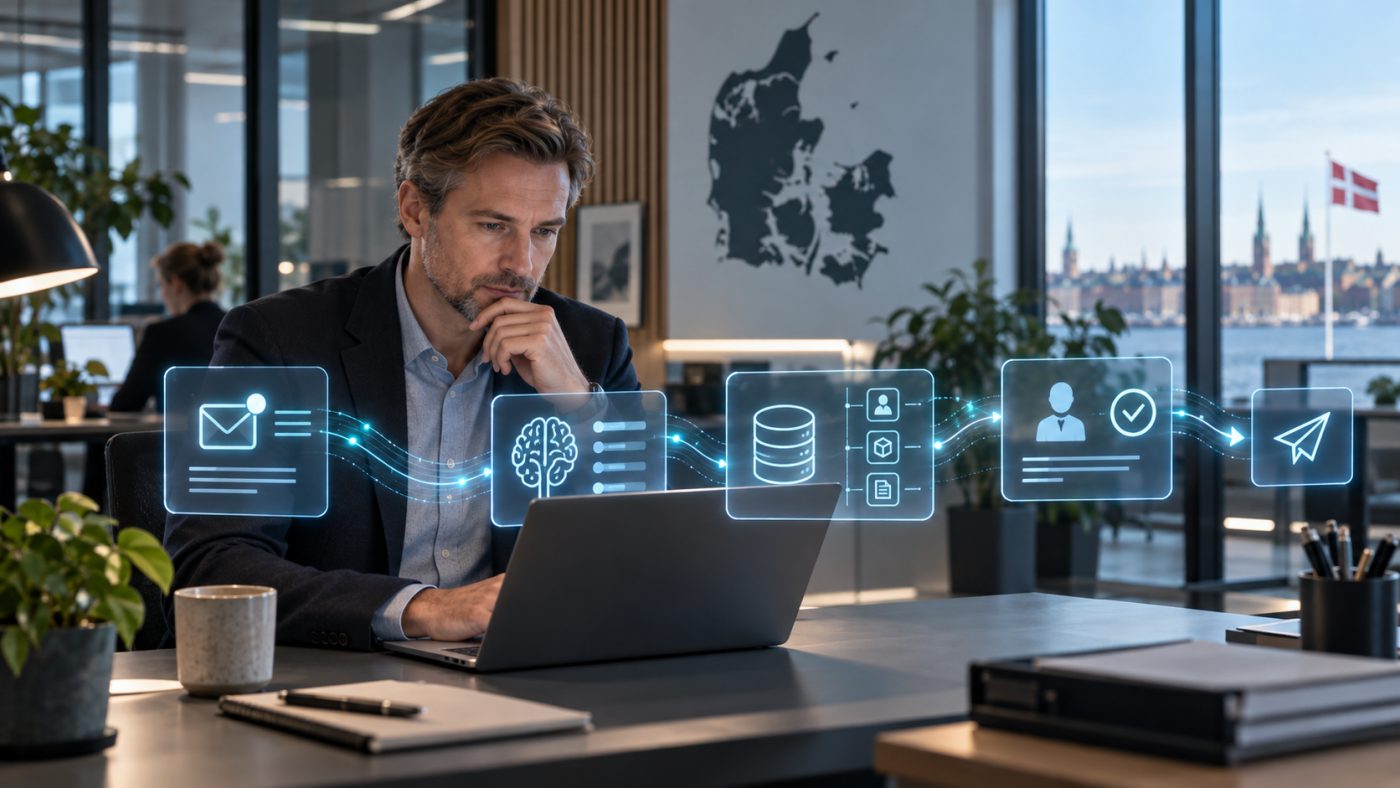
Take a perfectly ordinary workflow. A customer writes that a delivery is missing. The email contains a name, contact details, an order number and perhaps a long email thread.
An AI solution does not necessarily need access to the entire mailbox, every customer account and every function in the ERP system in order to help.
It can be built so that it first identifies the relevant enquiry, gets access to the necessary information and uses a language model to classify the case. A contained lookup in the ERP system can then retrieve the order status. Finally the system prepares a draft reply, which an employee reviews and approves.
Some parts can be handled with ordinary automation. Others can benefit from a small local model. And a few difficult cases may need a stronger model, or a person from the outset. This is not an example of a finished Sevren solution. It is an example of why more efficient models could matter in practice.
A security point worth understanding
An email is data from an external sender, not an instruction from the company's management. An AI agent can in some cases be tricked into following instructions hidden in the material it reads.
So a model that reads email should not at the same time have free rein to send messages, change customer data or retrieve confidential information unchecked. Let the model help with the assessment. Do not give it more rights than the task requires. I have written more about what separates a real agent from a workflow in the article on AI agents.
Is a smaller model also a cheaper solution?
Not necessarily.
The price of the AI inference itself is only one part of the sum. A company also pays for integrations, setup, server operations, updates, monitoring, error handling and the human oversight that is still needed.
A small model that handles 80 per cent of the simple cases well can be an excellent investment, if the rest is passed on sensibly. The same model can be an expensive mistake if staff spend more time correcting its answers than they used to spend doing the work.
Measure cost per correctly completed workflow — not cost per million tokens or a position on a model leaderboard. That is where technical efficiency turns into real business value. But only once quality has been tested on the tasks the company actually has.
How I would approach it in a company
- Pick one concrete workflow. Email triage, searching internal guidance, or extracting information from documents, for instance. Not "we need AI everywhere".
- Draw the data journey. What information comes in, where is it processed, which systems are contacted, and what is stored along the way?
- Settle the framework before you test with real data. Purpose, legal basis, confidentiality, supplier agreements and access control have to be considered from the start.
- Test with representative tasks. Compare a local model, an approved cloud solution if you have one, and ordinary automation. Measure errors, response time, human review and total cost.
- Grant limited access and keep control. Start with read access, log the relevant actions, and require approval before the system sends anything out or changes business-critical data.
Some companies will end up with a local solution. Others with a business agreement at a cloud supplier. Many will get the most out of a combination. The choice should be decided by the task, the data and the economics — not by what sounds most advanced.
Why I am following Sevren
There is a lot of talk about who has the biggest model, the most parameters and the best score on the latest test. That is relevant research. But it is not necessarily what a Danish company needs to know when it has to get a grip on its order inbox or automate a recurring administrative task.
If research like Sevren's leads to models that can handle more tasks on smaller and more controllable hardware, it opens up choices that do not exist today. How large the difference turns out to be in ordinary business solutions is not yet proven. And GDPR responsibility does not disappear, however efficient the model becomes.
But the possibility is worth following: more useful AI, closer to the data it has to work with. For me the measure of success is not how impressive a model is. It is whether it solves a real task safely, reliably and at a price that makes sense.
Do you have a workflow where AI could help — but the data makes you uneasy? I help companies map processes, assess data and integrations, and try solutions at small scale before investing in a larger project. Read about my AI advisory here.
Sources
- DCAI: the agreement with Sevren (9 September 2026)
- Sevren: launch and the first results (26 August 2026)
- Sevren: technical measurements for Heimr 570M (September 2026)
- The Danish Data Protection Agency: artificial intelligence and data protection
- EDPB: opinion on AI models and the GDPR
- The EU General Data Protection Regulation
Leave a comment
Got an experience, a counter-argument or a question? Do join in. Your email address will not be published.